
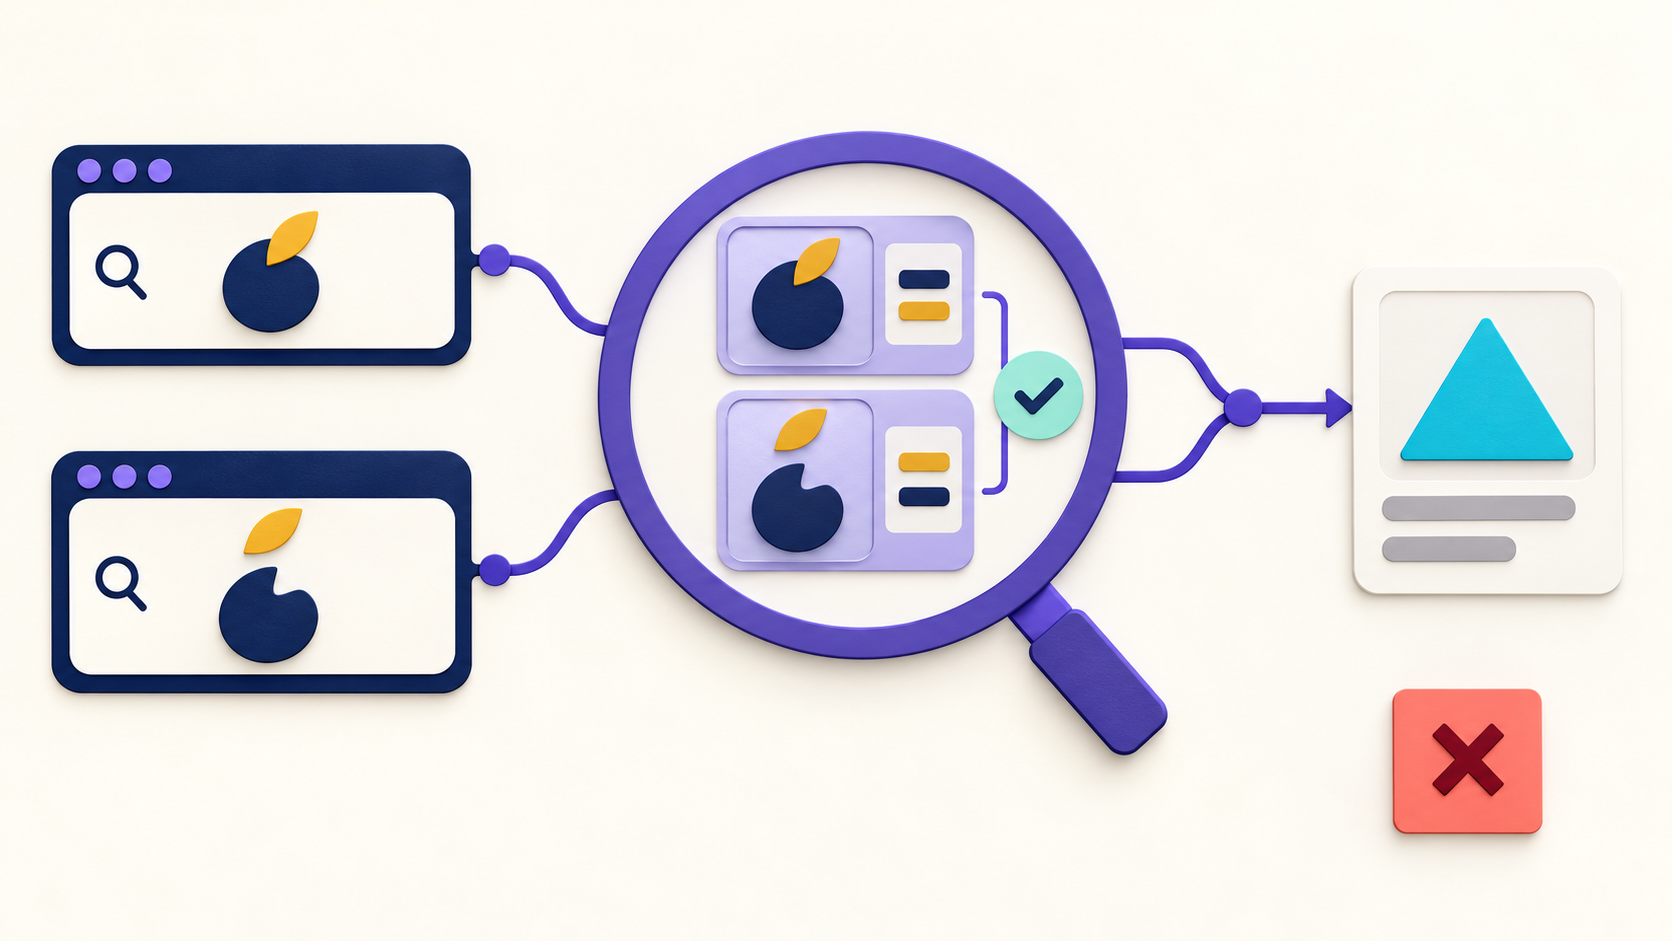
A brand query looks identical in two regional browser runs but returns different products. Before treating that as a residential-exit difference, compare the actual Unicode sequence. This guide gives authorized product-search and market-research teams a controlled way to distinguish query normalization from routing, indexing and result presentation. It is a test design, not a report of measured 98IP behavior or real search rankings.
1. Define equivalence with the search owner
Unicode permits canonically equivalent sequences: an accented letter may be one precomposed character or a base letter followed by a combining mark. NFC and NFD provide different canonical normalized forms. Compatibility normalization such as NFKC can remove additional distinctions and must not be applied blindly. Normalization is not the same operation as removing accents, translating text or case folding.
Ask the owner which query pairs should yield equivalent results, and which must remain distinct. Define a small synthetic catalog with independent expected product IDs, locale and market. If the service intentionally performs exact sequence matching, record that contract; do not call every NFC/NFD difference a defect or modify third-party search inputs without permission.
2. Construct reproducible input pairs
- Create a pair using U+00E9 and U+0065 followed by U+0301 in the same synthetic word. Generate the strings from code points rather than typing two visually similar labels and assuming their representation.
- Save the code-point sequence and UTF-8 bytes in a non-secret fixture manifest, together with the owner's expected equivalence. A screenshot cannot establish the sequence.
- Add a deliberately different control, such as the unaccented word, with its own owner-approved expected result. Do not assume it belongs to the same equivalence class.
- Fix client version, keyboard/input method, language, market, account state, search settings and region. Use the same submission action in each run.
- Keep a raw fixture value and a separately labeled normalized diagnostic copy. Do not overwrite the original before observing what the application does.
For a JavaScript test harness, String.prototype.normalize with an explicit form can construct a diagnostic comparison. That confirms string equivalence under that form, not the search engine's indexing or ranking contract. Record the runtime and form, and never use a visual character count as a substitute for code-point evidence.
3. Trace the query across four boundaries
On an owned staging application, capture the input value immediately before submission, the serialized request representation, the receiver's decoded query, and the search layer's actual lookup key if the owner exposes it. Correlate each attempt independently. Use synthetic values only; raw customer search histories do not belong in shared debug logs.
Encode a query component through the client's normal URL or body serializer once. Percent encoding and Unicode normalization are different transformations. Compare decoded strings and serialized bytes separately; do not repeatedly decode a whole URL, where an encoded separator may be actual data. A receiver showing percent signs instead of the intended text may indicate a serialization boundary error rather than an index issue.
Check whether display formatting, autocomplete selection or input-method composition changes the submitted value. Test typing and paste as separate approved actions when both matter. Submitting while composition is incomplete is a different input from the committed query and should not be treated as a regional result comparison.
4. Compare result identity before comparing counts
Run the pair and negative control through an approved baseline and selected proxy route, with a small fixed attempt budget. Keep market, locale, filters and session policy unchanged. Record the actual egress, fixture/index version, submitted code points, decoded receiver value and returned product IDs.
- The owner expects equivalence, both received queries are correct, but IDs differ: investigate search analysis, index ingestion or cache keys with the owner.
- The receiver sees a different sequence from the committed input: investigate the first observed client or serialization boundary that changed it.
- Product IDs match but ordering or labels differ: classify ranking or presentation separately; equivalent identity does not prove identical ranking.
- Market or fixture version differs: the comparison is confounded. Restore the control before blaming normalization or the exit.
A 200 response and equal result counts are insufficient: two different product sets can have the same size. For the synthetic fixture, compare the defined IDs and only require order when the owner's contract makes order part of acceptance. If a direct baseline is prohibited, state that limitation explicitly.
5. Repair only the agreed normalization boundary
If you own the application and its contract requires canonical matching, choose and document the normalization form and apply consistent rules to the query and indexed lookup representation. Keep original text for display or audit where required. Changing only the query may leave old indexed records incompatible; plan the owner-approved reindex or migration and verify old and new fixtures.
Do not normalize passwords, signatures, opaque tokens or product identifiers as a side effect of a search repair. Do not strip accents or apply NFKC merely because it broadens matches. Add a negative control that must stay distinct and check that the repair has not merged it. Key caches and deduplication under the same documented search semantics; otherwise equivalent queries may retain conflicting old results.
For a third-party research target, preserve the approved input policy and report observed behavior without silently merging records. A normalized deduplication key is an analytical choice, not proof that two real products or users are identical. Never fabricate search volume, rankings or regional preference from these synthetic cases.
6. Use 98IP for the regional control
The 98IP dynamic residential IP page is relevant when the authorized search must be checked from selected customer regions. Obtain supported connection details from the configuration documentation and your account. Verify actual egress and keep region and session settings stable during a string comparison.
A regional route can expose different deployments or index versions, but it does not normalize your text or guarantee identical search results. In ordinary non-intercepting HTTPS, the proxy cannot rewrite the encrypted query. No measured throughput, client compatibility or failed-request billing result is promised here. Limit traffic, check actual usage and collect only authorized data.
7. Acceptance checklist and FAQ
- The owner defines canonical-equivalent pairs and a control that must remain distinct.
- Committed input, serialized bytes, decoded query and lookup key are separately observable or marked unknown.
- Fixture version, market, locale, filters, browser and session policy stay fixed.
- Expected product IDs pass; counts, ordering and display claims are evaluated separately.
- Repair preserves original values where required and does not alter secrets, tokens or unrelated identifiers.
Can screenshots prove equal input? No. Inspect code points and the committed value; identical appearance can hide different sequences.
Should every query become NFKC? No. Compatibility folding can erase meaningful distinctions. The owner must approve the intended search semantics and negative controls.
Does NFC guarantee equal results across countries? No. Market selection, index contents, filters and ranking can differ. Normalization tests control one variable, not the entire regional search experience.
Related Recommendations
- Regional Proxy CSV Export Checks: Validate Records Before Opening the Spreadsheet
- How to Test HTTPS Proxy TLS and Cipher Compatibility Before Purchase
- Regional Proxy Image Checks: Validate the Asset the Browser Actually Selected
- What are the functions of the http proxy IP tool? How to set the proxy IP address for mobile phone software?
- Proxy 304 Responses: Reuse the Right Local Copy, Not an Empty Body
- Preventing agent retry storms: backoff, jitter, budgeting and security recovery
- How to Validate HTTP Range Requests and Resumable Downloads Through a Proxy
- Proxy Pagination Data Integrity: Find Duplicate and Missing Records
- How to Design Proxy Timeout Budgets for Reliable Automation
- Residential Proxy Session Stickiness Test: Measure Stability Before You Buy