
Your regional landing page opens through a residential proxy and shows the right language. That does not tell you whether the delivered response carries an unintended indexing restriction. A regional edge configuration can serve the right body alongside a noindex header, while a page template can add a conflicting HTML rule.
This guide is a release acceptance plan for owned or explicitly authorized sites. It checks the indexing instructions delivered on selected regional routes. It does not impersonate a verified search crawler, prove Googlebot sees the same response, or guarantee indexing, traffic or rankings.
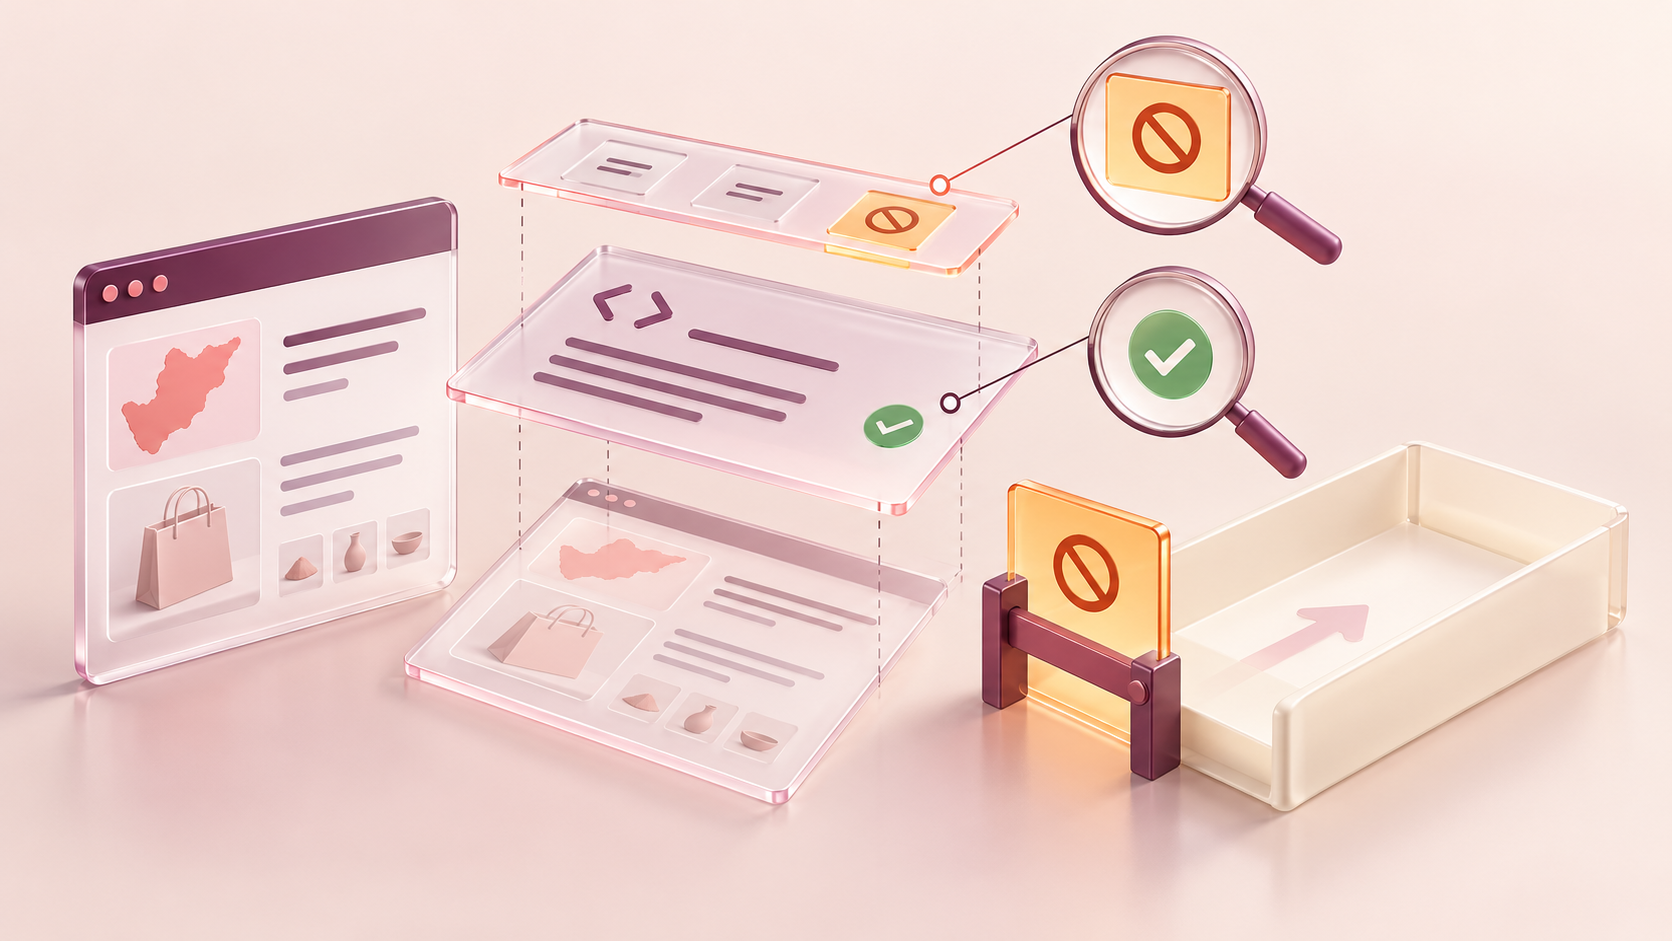
1. Write a per-URL expectation before fetching
Make a small approved URL list covering a public landing page, one localized product page and an intentionally excluded test page. For each, record the final expected host and path, intended indexing policy, language, application build and environment. Do not assume every page should become indexable.
Keep three outcomes distinct: page delivery, delivered indexing instructions and actual search-engine index status. This test can establish the first two for its observed routes. The third requires separate evidence from the site's authorized search tooling and cannot be inferred from HTTP 200 or a sitemap entry.
Define the crawler whose policy you are assessing. Google's Search Central documentation describes rules for Google; other search engines may interpret settings differently. Ordinary browser route checks remain useful, but changing a user-agent string does not turn a residential proxy into a verified Google crawler.
2. Capture the final GET response
- Use an approved baseline route, fixed browser or HTTP client configuration, no login unless required by the case, and a small request budget.
- Request each URL with GET, record redirects, and identify the final response. A rule on a redirect is not evidence of the final document's rule.
- Save sanitized response headers and the original HTML from that same request, together with status, content type and final URL.
- Confirm the expected page identity and language. A challenge or login page behind 200 is a delivery failure for this fixture, not a successful audit of the intended landing page.
- Repeat on each approved regional proxy route, changing only the route first. Keep cookies, locale and client configuration controlled.
The 98IP dynamic residential IP page helps identify a product for authorized regional delivery checks. Use the API configuration page to verify current connection methods and account options. Neither page guarantees a search crawler's route or how a search engine will index a destination.
3. Inspect header and HTML instructions independently
For this Google-focused check, inspect both X-Robots-Tag response headers and applicable robots metadata in the HTML. Record all occurrences, including rules targeted to a specific crawler. Do not stop at the first permissive rule: conflicting applicable rules can leave a restriction effective. Google documents the more restrictive treatment of conflicting rules.
Use a header-aware parser that retains repeated header fields and an HTML parser for metadata. Do not search only for the exact lowercase substring noindex, or accept the word index merely because it appears somewhere in the document. Quoted examples, script strings and article text are not automatically operative metadata.
Keep the raw rule text, its location and its applicability in the evidence table. A generic robots rule and a crawler-specific rule need separate entries. If an instruction is unfamiliar or malformed, flag it for documented interpretation instead of silently declaring permission.
4. Compare source HTML with the observed rendered document
If your application changes metadata using JavaScript, capture the original HTML and a bounded rendered observation separately. Wait for a declared application-ready condition, then list the relevant metadata present in the document. Record the browser, deadline and whether readiness was actually reached.
A difference between source and rendered metadata is a configuration finding, not proof of what a particular search engine ultimately processed. Do not assume a later client-side change canceled an earlier response header. Route the mismatch to the application or edge owner and confirm the intended rule at every layer.
Use four comparison columns per case: delivered page identity, applicable header rules, source HTML rules and rendered metadata. Mark an incomplete render as incomplete. Avoid replacing missing evidence with a screenshot of the page body.
5. Check discovery and crawl controls separately
Google's noindex documentation explains that the crawler must be able to access a page to see its noindex instruction. A robots.txt disallow is therefore not a substitute for delivering noindex to that crawler. Do not add a disallow just to hide an accidental rule from inspection.
For owned pages, review the relevant crawl policy and sitemap membership as separate release checks. Being present in a sitemap does not override noindex or guarantee indexing. Likewise, the absence of noindex does not establish that a page will be selected for search results.
Keep private staging content behind real access controls. An indexing instruction is not authentication. This audit does not authorize exposing a private environment or altering live crawl controls; it records delivered configuration for the site's owners to review.
6. Exercise a small regional fault matrix
- Public fixture, all selected routes: expected document loads and no unapproved applicable restriction appears.
- Intentionally excluded fixture: the approved noindex policy remains present; the test must not demand its removal.
- Owned staging edge injects a restrictive header on one route: the header column detects it despite a permissive HTML template.
- Template adds a second restrictive metadata rule: the audit records both entries rather than accepting the first one.
- Rendered metadata diverges from source: report the layer mismatch with readiness evidence, without claiming actual indexing behavior.
- Challenge, redirect to login or timeout: fail delivery or mark the case incomplete; do not count it as a clean indexing-policy result.
These are proposed cases, not executed measurements. After the owner corrects an unexpected rule, repeat the affected URL and selected baseline routes using the same fixture contract. Confirm the delivered configuration first, then review actual search status separately; do not report instant reindexing after a successful proxy retest.
FAQ and release checklist
Does HTTP 200 mean the page is indexable? It only establishes a response status. Verify page identity and applicable rules separately.
Does a residential route reproduce Googlebot? No. Treat it as a regional delivery observation with its own client settings and limits.
- Each URL has an explicit intended policy and environment.
- The final GET response, not just a HEAD or redirect, is inspected.
- Repeated headers, metadata and crawler applicability are preserved.
- Source and rendered evidence remain separate.
- Intentionally excluded pages and private environments stay protected.
- Reports contain sanitized evidence and no unsupported indexing, ranking or traffic claims.
Related Recommendations
- Proxy Connection Pooling: Performance, Reuse, and Isolation
- SOCKS5 vs socks5h: How Remote DNS Changes Proxy Routing
- Residential Proxy Evaluation Checklist: 7 Tests to Run Before You Buy
- How to Test Residential Proxy ASN Targeting Before You Buy
- How to set a computer to access the Internet with static IP? Here are the detailed steps
- How to Audit Residential Proxy Provenance Before You Buy
- Proxy Response Integrity Test: Detect Truncation, Decompression Errors, and False Success
- How to Audit Proxy Bypass and PAC Rules in Browser Automation
- How to Prevent Clock Skew from Corrupting Proxy Latency and Session Metrics
- Proxy Credential Encoding Validation: Prevent 407 Errors and Secret Leaks