
Proxy requests keep returning successful responses, but the parser or result store falls behind. The uncommitted output queue grows, memory rises and restarted workers fetch the same pages again. Control admission using downstream capacity as well as request concurrency. This guide proposes a bounded workflow for authorized collection and website checks; it does not claim a tested throughput improvement, lower bill or a built-in 98IP buffering feature.
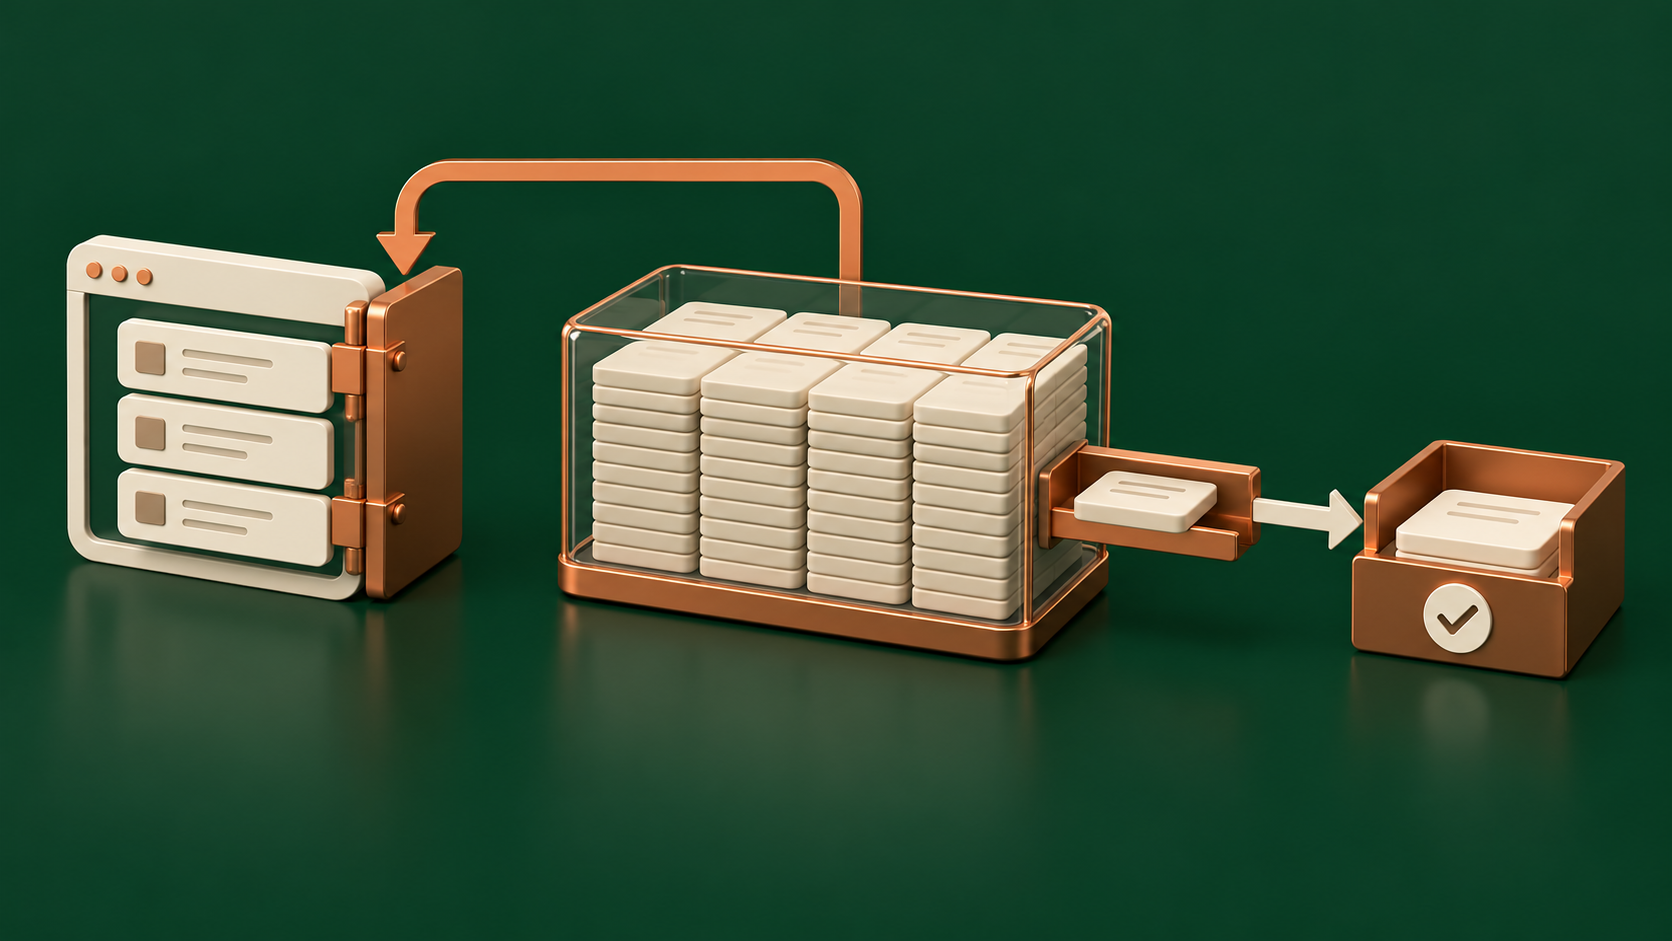
1. Locate the slow stage before adding proxies
Draw the actual sequence: request admission, response reading, parsing, validation, pending output, durable write and acknowledgement. Record rates at these boundaries using the same time window. HTTP success is an input to the pipeline, not evidence that a usable record reached the intended store.
Measure queued item count, queued bytes on a defined basis, oldest pending age, in-flight work and acknowledged output rate. Keep parsed-object memory, serialized output bytes and provider-measured traffic distinct. A small saved JSON file does not establish the memory required by its source response or browser.
If requests complete faster than the sink can commit results, increasing proxy concurrency can increase the backlog. First confirm whether the bottleneck is parsing, validation, storage latency, downstream throttling or repeated write failures. Do not classify every slow result as a proxy availability problem.
2. Define a capacity budget with room for in-flight work
Choose owner-approved high and lower resume thresholds for the pending-output budget. Pause new fetch admission when the high threshold is reached; resume only after the queue drains below the lower threshold and the sink is healthy. Different thresholds reduce rapid stop-start oscillation. Their values need workload evidence, not a universal record count copied from another project.
Reserve capacity for responses already admitted but not yet represented in the output queue. If a pending queue contains Q measured units and in-flight work can still add up to R on the same basis, compare Q + R with the approved budget before admitting more. Release reservations only as the corresponding work is settled or safely accounted for.
For a synthetic illustration, suppose the comparable budget is 100 units, queued output is 70 and admitted work may still add 25. A new request needing a 10-unit reservation does not fit: 70 + 25 + 10 exceeds 100, even though the visible queue alone looks below the limit. These are invented internal units, not measured memory, proxy traffic or 98IP capacity.
If response size is unbounded, an estimate cannot provide a hard memory guarantee. Use appropriate response and parser limits, bounded batches or a reviewed durable spool. Include overhead and failure behavior in the design. Stream high-water thresholds are coordination signals, not proof that the entire application has a strict global memory cap.
3. Propagate pressure back to request admission
- Before scheduling a new proxy request, check the downstream budget, sink health, job scope and remaining business validity. Keep this admission decision coordinated across workers sharing the same buffer.
- When the high threshold or a sink failure is reached, stop admitting new fetches. Preserve accepted records and continue the approved drain or recovery path rather than dropping them to make the dashboard green.
- Respect the runtime's supported stream or writer backpressure mechanism where used. Do not keep appending to an unbounded application array after the stream asks its producer to wait.
- Account for already-running requests. Pausing the scheduler does not cancel them or prevent all remaining bytes; retain their reservations and use a supported cancellation policy only when required.
- Let the sink acknowledge according to its documented durability contract. Remove pending records and advance a recoverable checkpoint only when the relevant output has been confirmed.
- Resume gradually below the lower threshold after verifying sink recovery. Recheck each job's original validity and identity; do not release a burst of expired observations merely because storage became fast again.
A stream library can coordinate its connected stages, but it does not automatically regulate every independent job queue or browser worker in your service. Verify that the pause signal reaches the component that starts network work. Otherwise the application can keep downloading while merely moving the backlog to another buffer.
4. Rehearse a slow sink and an unavailable sink
Use an owned synthetic source and test-only output store. Give records stable logical identities and known content. Define exact admitted-request counts, retained pending records and committed results before the test. These are proposed acceptance cases, not an executed benchmark.
- Run a small normal fixture and confirm the correspondence between admitted requests, validated records and acknowledged writes.
- Deliberately slow the test sink while leaving the source unchanged. Confirm the pending budget rises to the pause condition, then new fetch admission stops while the sink continues draining.
- Observe in-flight completions after the pause. Verify they were included in the reserved budget rather than concluding that all traffic stops instantly.
- Make the test sink unavailable. Confirm the system records the reason, keeps bounded pending work and does not retry both fetches and writes indefinitely.
- Restore the sink and drain below the resume threshold. Confirm gradual resumption, valid original job deadlines and no missing or duplicate committed logical records.
- Lose one test write acknowledgement or restart one worker. Reconcile output through the store's supported identity and readback semantics before repeating a write or fetching the source again.
Use test-only fault injection approved by the owner. Do not fill a production disk, throttle a shared database or disconnect customer traffic to demonstrate backpressure. Keep the rehearsal small enough that its own recovery remains bounded.
5. Recover pending output without inventing delivery guarantees
Separate a confirmed write failure from an unknown write outcome. A lost acknowledgement can mean the record was committed. Use supported deduplication or readback by logical identity before replay, and document what the output store actually guarantees. A local retry loop does not create universal exactly-once delivery.
When the source result is already validated and safely retained, prefer recovering its pending output over fetching the page again merely because the sink was slow. If the retained record is incomplete, expired or unavailable after a crash, classify that condition explicitly and follow the owner's policy. Do not pretend a later refetch is the same earlier observation.
A durable spool needs capacity, access, retention and cleanup rules of its own. Avoid temporary files that grow without bound or contain unnecessary customer data. If the spool becomes unsafe or full, stop new admissions and retain a visible recovery state; do not silently discard results or route them to an unapproved store.
Useful incident evidence includes job and record IDs, counter definitions, threshold revisions, occupancy, in-flight reservations, pause/resume times, sink errors and verified commit outcomes. Exclude proxy credentials, tokens, cookies and sensitive response bodies. Keep per-project fairness separate; the shared proxy queue isolation guide covers competition between projects rather than the sink's capacity.
6. Connect throughput decisions to real 98IP usage
For authorized market research, ad verification or website testing, consult the 98IP residential proxy product page and API configuration documentation. Use a supported account method, keep session policy appropriate to the job and compare actual traffic with verified usable output.
A proxy route does not make a parser or database faster, acknowledge durable storage or enforce your application's output budget. Before adding more request capacity, establish whether the sink can accept it. Backpressure is intended to keep admitted work within a controlled pipeline; any claimed cost or performance benefit still requires measurement under the actual account and workload.
- Request completion and durable usable output are counted separately.
- Pending bytes, item counts, oldest age and in-flight commitments are visible.
- High and lower resume thresholds use a documented measurement basis.
- A pause actually reaches the network admission boundary.
- Slow, failed and uncertain sink cases preserve bounded recoverable state.
- Resumption checks identity and job validity without blind refetch or write replay.
Does low HTTP concurrency guarantee bounded output memory? No. A slow sink can accumulate completed results over time, and record sizes vary.
Should we drop queued records when the sink is slow? Not as an invisible fix. Follow the approved retention and recovery policy and report any loss explicitly.
Does a stream high-water setting solve the whole service? No. Check all application queues, in-flight work, parser limits and the actual dispatch path.
Related Recommendations
- How to Test WebSocket Connections Through a Proxy
- How to Audit Proxy Geolocation Database Freshness Before a Regional Launch
- Stop Expired Proxy Jobs Before Dispatch: Preserve the Observation Window
- How to Test TLS Certificate Revocation Through a Proxy
- Proxy Pool Quarantine and Recovery: Stop Unhealthy Exits From Returning Too Soon
- How to Test GeoDNS Consistency Across Proxy Markets
- How to Audit ASN and Prefix Concentration Before Buying a Proxy Pool
- Same File Will Not Retry Through a Proxy? Test Selection, Cancel and Clear
- Static Residential Proxy Renewal: Verify the Allocation and a Fresh Connection
- RTL Product Codes Look Reversed? Test Identifier Boundaries Through Regional Proxies